Zero-shot stance detection in practice: insights on training, prompting, and decoding with a capable lightweight LLM
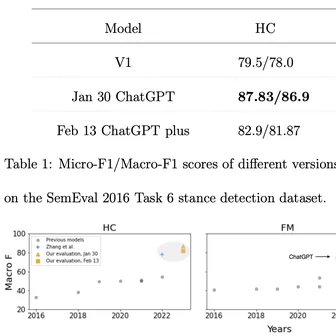
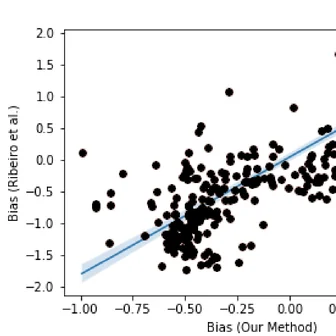
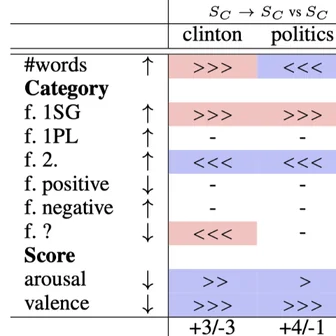
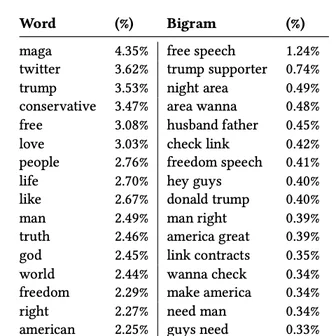
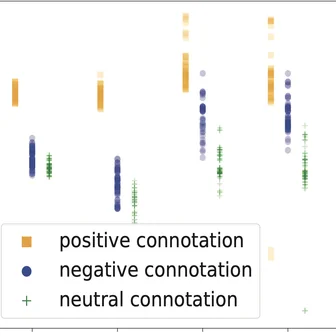
Can LLMs do stance detection on tweets without any fine-tuning? Using FlanT5-XXL with SemEval 2016 and P-Stance datasets, we find zero-shot prompting matches or beats fine-tuned baselines. Performance varies with prompt phrasing, decoding strategy, and a measurable positivity bias, and we surface cases where the LLM over-commits to a stance when none is actually present.